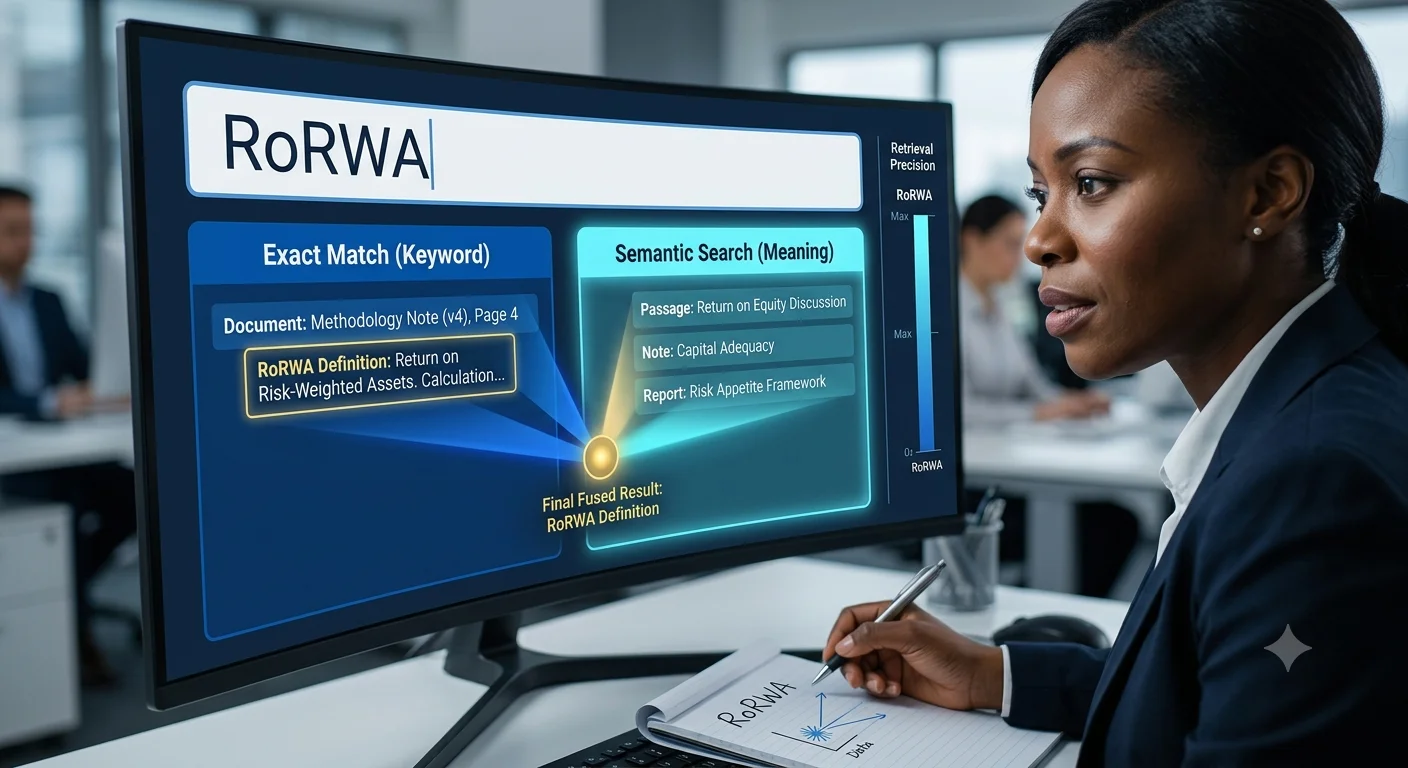
A credit analyst opens the new assistant and types one word: RoRWA.
She wants the definition the bank actually uses — return on risk-weighted assets, how the denominator is averaged, which capital charge sits underneath it. It’s in a methodology note, on page four. She’s read it before. She just wants it back.
The assistant returns five passages. One on return on equity. One on capital adequacy. One on risk appetite. A paragraph about RWA optimization from a strategy deck. A note on return metrics for the retail book. All of them are about roughly the right subject. None of them is the document that defines the term she typed.
She doesn’t file a bug. She closes the tab and concludes the system doesn’t know her business. That conclusion is harder to reverse than any wrong number.
Most enterprise AI builds retrieve context the same way. Every chunk of every document is turned into an embedding — a list of numbers that places text by its meaning. The question gets the same treatment, and the system returns the chunks whose meaning sits nearest.
For natural-language questions, that works remarkably well. “How do we treat undrawn commitments?” finds the right passage even if the document says “off-balance-sheet facilities”. That’s the point of semantic search: it matches what you meant, not what you typed.
The trouble is that specialists don’t always mean something. Often they name something. RoRWA. A product code. A facility identifier. A ratio with a house-specific definition. A regulation cited by article number. To an embedding model, these strings are close to noise — rare tokens, little surrounding context, often split into fragments it has never seen together. So it does the only thing it can: it finds text about the neighbourhood. Return metrics. Capital. Risk.
The result is a peculiar failure. The system is best at vague questions and worst at precise ones. And the precise questions come from exactly the people whose trust a rollout depends on — the analyst, the risk manager, the product controller. The more expert the user, the worse it performs.
It also fails quietly. Nothing errors. Five plausible passages come back, ranked with confidence, and if a model then writes an answer on top of them, it will happily explain RoRWA using a definition of return on equity. The reader may not catch it. Worse, they may.
The fix isn’t a better embedding model. It’s recognising that “find the passage that contains this exact term” and “find the passage that means this” are two different retrieval problems — and that most pipelines ask one method to do both.
Keyword search — the old, unfashionable kind that ranks documents by how often and how distinctively a term appears — is very good at the first job. It doesn’t know that “undrawn” and “off-balance-sheet” are related. But it knows, with certainty, which documents contain the string RoRWA, and it knows that a rare term appearing three times in a short methodology note is a strong signal. Exact identifiers are where it is strongest, and where meaning-based search is weakest.
Hybrid retrieval runs both. The same question goes to keyword search and to semantic search in parallel. Each returns its own ranked list. The two lists are then fused into a single ranking, typically by rewarding passages that rank well on either list — and most of all those that rank well on both.
Run the analyst’s query again. Keyword search puts the methodology note first, because it’s the only document that defines the term. Semantic search contributes to the surrounding context — the capital adequacy passage, the note on how RWA is calculated — which is genuinely useful once the definition is in hand. The fused list leads with the right document and follows with the right neighbours. Neither method gets there alone.
And for the ordinary question — “how do we treat undrawn commitments?” — nothing gets worse. Keyword search contributes little, semantic search carries the result, and the fusion lets it.
We learned this the expensive way, so it’s worth stating plainly.
None of this is novel. Keyword search is decades old. What’s new is how many teams dropped it in the rush to embedding, and how many pilots now stall on the gap it used to cover.
An enterprise assistant isn’t judged on its best answer to a broad question. It’s judged on the first time an expert types a term they know cold and watches what comes back. Get that right and they’ll forgive a lot. Get it wrong and they won’t type a second one.
Your search should be able to spell RoRWA. In Equative Insights OS, it does — hybrid retrieval is the default, not an upgrade.